Why a Readiness Score Needs a "Not Enough Data" State
By Mr.Apps · Sep 18, 2026
Category:Recovery

A blank result can be the accurate result
I do not regard a missing readiness score as a failure by default. Sometimes the data do not support a responsible estimate. Overnight wear may be incomplete, the relevant signal may be corrupted, sources may disagree, or the baseline may be too unstable. In those cases, a confident-looking number hides the most important fact: the system does not know enough.
A “not enough data” state is a quality feature. It tells the user that the calculation has a boundary and that the next decision should be based on other information or a better record.
The alternative is often worse. A fallback score can make a gap look like normal variation and encourage the user to act on an output that was never properly supported.
Missing, conflicting, and noisy are different
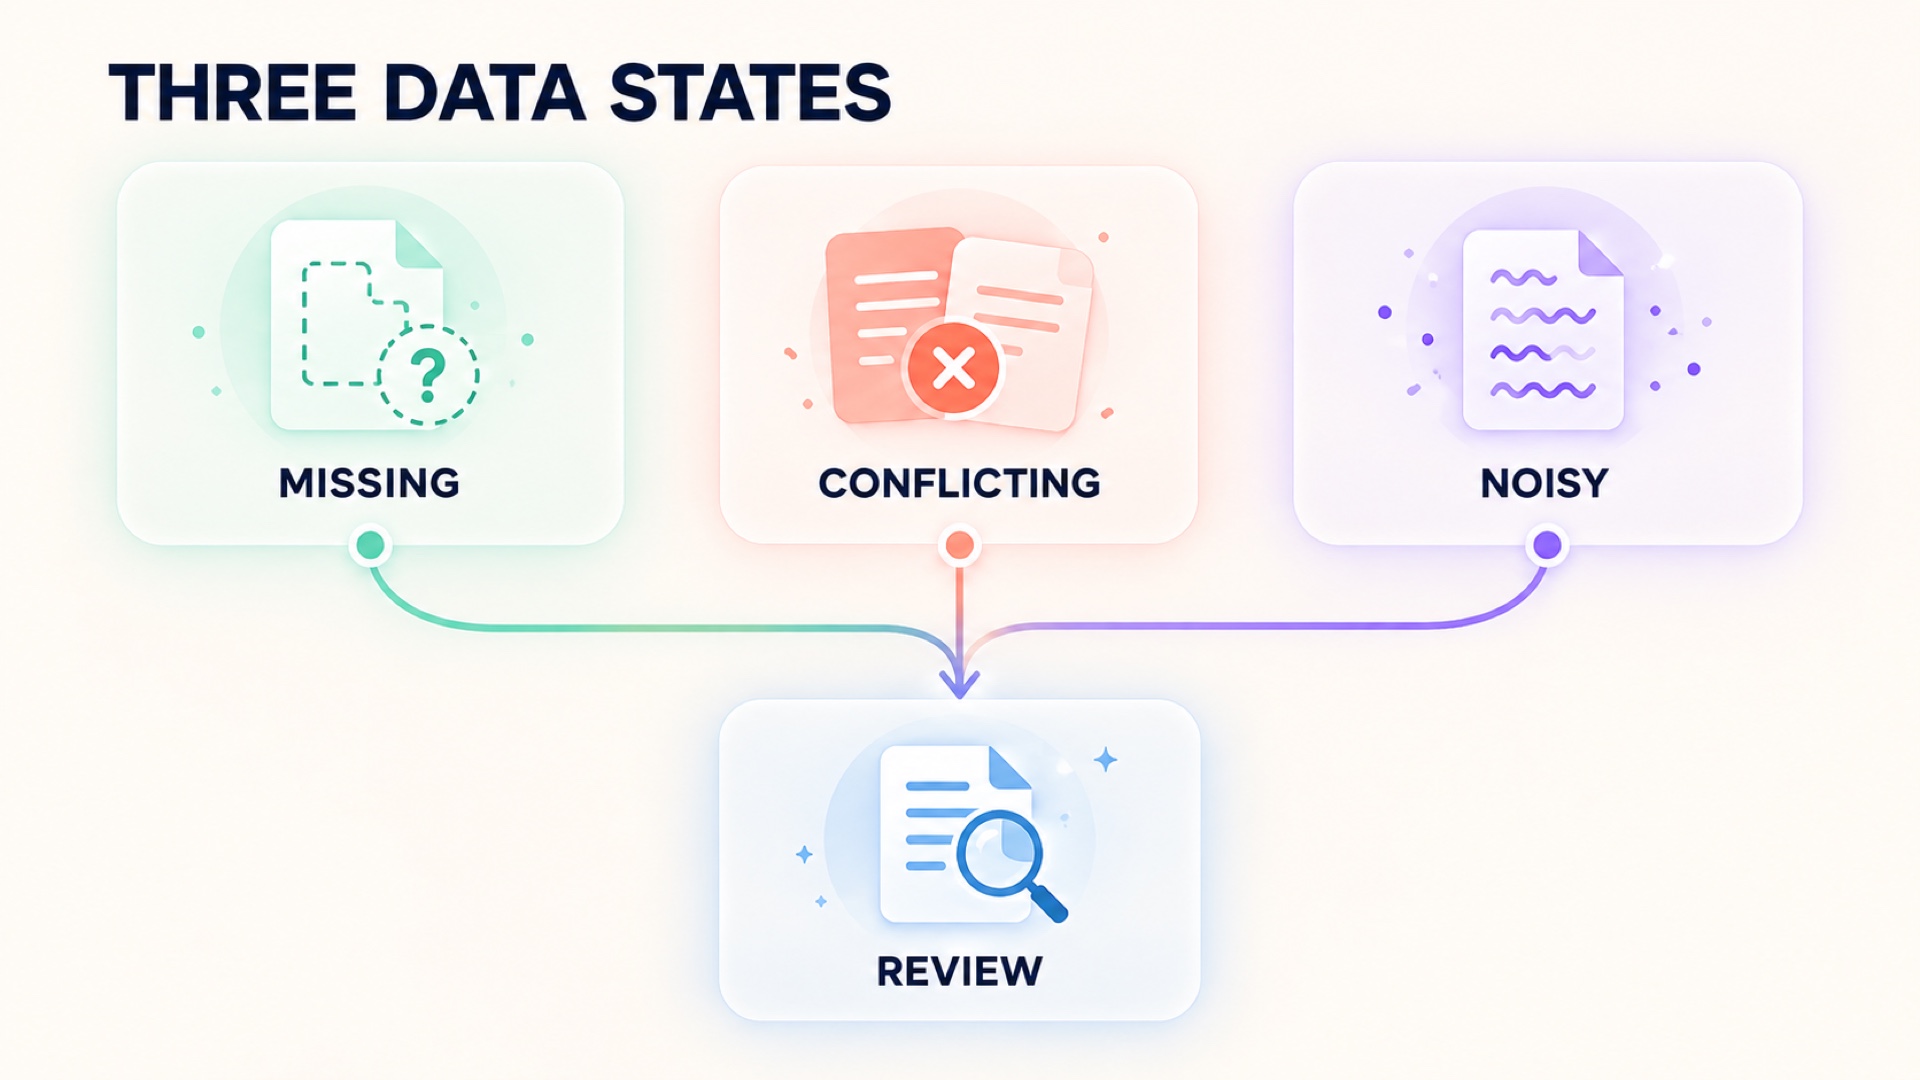
The app should explain why it withheld the score. Missing data means an expected input was not recorded. Conflicting data means sources or signals disagree. Noisy data means values were recorded but cannot be separated reliably from artifact or instability. These conditions may lead to the same user-facing state, but they need different remedies.
Missing data might call for more wear time or a sync check. Conflicting sources might call for source selection or a timestamp review. Noisy data might call for a fit adjustment, a repeat observation, or a decision not to interpret the period.
The message should be specific without being technical for its own sake. “Overnight recovery estimate unavailable because the record is incomplete” is better than “score error.”
Do not confuse availability with validity
Software can produce a number from almost any collection of inputs. That does not mean the number is valid for the intended decision. A calculation can run successfully while the evidence is too sparse, too unusual, or too different from the baseline.
This is a central difference between computation and interpretation. The app may be able to multiply, average, or classify the values, but the user needs to know whether the result should guide a plan.
An evidence framework for consumer wearable validation emphasizes target population, criterion measure, testing conditions, processing, and analysis. Those domains show why a technically available output can still be limited in use.
Show the threshold for withholding
An app should disclose, in plain language, what makes data sufficient. It may require a minimum wear period, a usable signal window, a stable baseline, or agreement between required inputs. The exact threshold can remain part of the implementation, but the user should know the type of condition being checked.
The threshold should also be honest about uncertainty. A score might be available with reduced confidence rather than fully withheld. If the app uses confidence levels, it should explain what they refer to and whether the recommendation changes at each level.
The worst design is a hidden fallback. If incomplete data produce the same screen as a complete record, the user cannot tell whether the score is comparable with earlier days.
Keep the raw record visible
Withholding a score should not erase the underlying data. The user may still want to review the recorded sleep period, heart-rate trace, activity, or sync status. The app should separate the raw record from the unavailable interpretation.
This separation supports correction. If the user later restores a missing source or fixes a time stamp, the app can recalculate without pretending that the original score was always valid. A visible history of the change also helps the user understand why the number appeared later.
If a score requires overnight wear, review why overnight coverage is part of making a readiness estimate useful. The state of the input should be visible before the final score is interpreted.
Use other information without replacing the score
When the score is unavailable, the app can still offer a safe next step. It might suggest checking the data connection, reviewing the recorded window, repeating the observation, or using the user's planned decision rules. It should not invent a substitute score from unrelated inputs unless that alternative has a clearly defined purpose.
The user can also consider symptoms, function, and recent context. This does not turn a missing score into a diagnosis. It simply recognizes that the dashboard is one information source and that its absence does not remove the need for a decision.
The app should avoid language that pressures the user to complete more collection merely to unlock a number. More wear is useful only when it improves the relevant evidence and remains acceptable to the user.
A score should explain its refusal
The phrase “not enough data” should include a reason, a next step, and a limit. The reason identifies the missing or unreliable condition. The next step tells the user what can be checked. The limit states what the app cannot responsibly infer yet.
For example, the interface might say that the overnight window is incomplete, recommend checking fit and sync, and state that the recovery score will be withheld until a comparable record is available. That is more helpful than a number with a footnote.
The refusal should be recorded in the history. If the same problem repeats, the user can recognize a pattern and decide whether the device or workflow needs attention. Repeated silence is a data-quality signal of its own.
Confidence should change the available action
The purpose of a confidence state is not to decorate the score. It should change how the app frames the next step. A complete record may support a cautious comparison with the user's baseline. A partial record may support only a data-quality check. A noisy record may support no readiness conclusion at all.
If the same recommendation appears at every confidence level, the label is not doing meaningful work. The user needs to know when the output is strong enough to inform a plan and when it is only a prompt to wait or review.
Do not hide uncertainty inside a replacement score
An app may be tempted to fill a missing recovery input with an average, a previous value, or a model prediction. Such methods can be defensible in a defined context, but the substitution must be disclosed. Otherwise, the user may believe the score came from a fresh observation when it did not.
The interface should identify an imputed or carried-forward value and explain whether the final score is comparable with a normal day. If the substitution changes the use of the score, withholding it may be better. The reporting guidance for diagnostic accuracy studies illustrates why missing data and participant flow matter to the credibility of a result.
The central rule is simple: never let the convenience of a filled card outweigh the truth about the record.
Make recovery from the gap easy

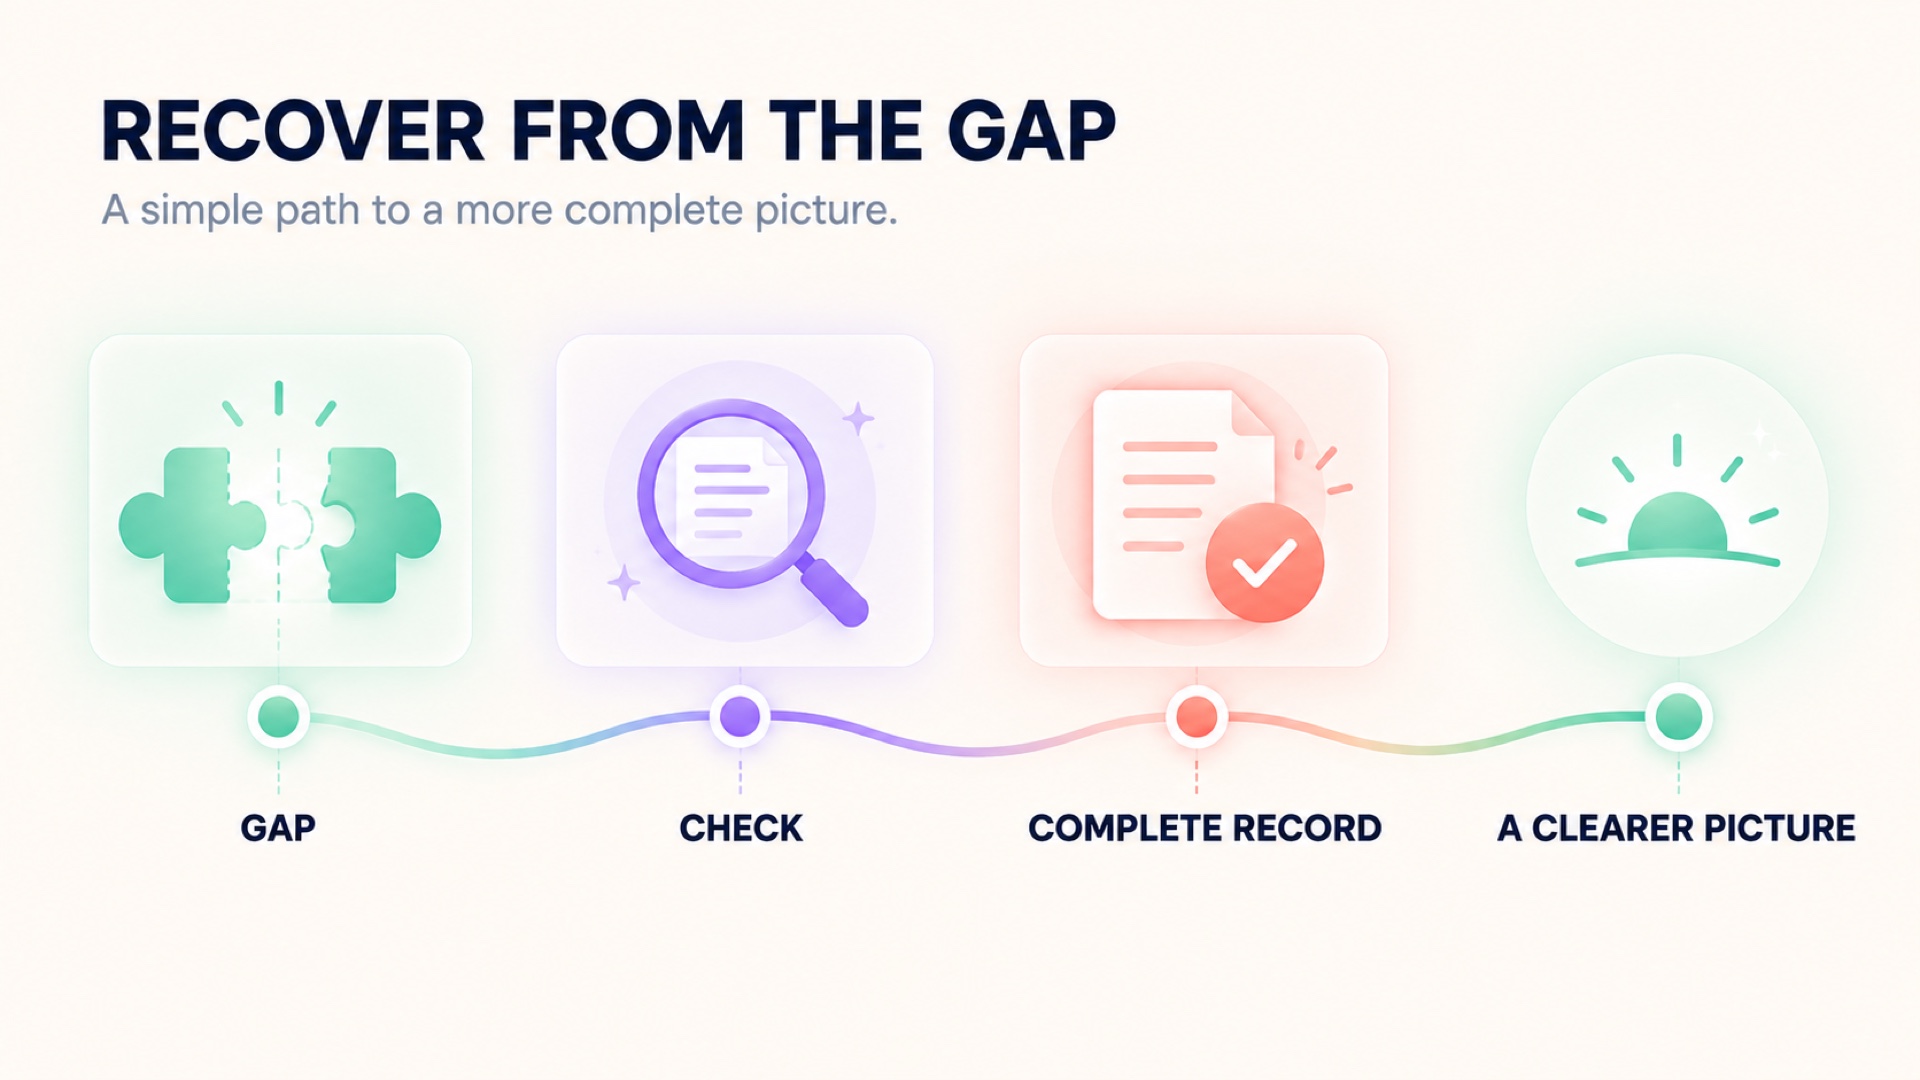
The best unavailable state gives the user a short route back to a valid comparison. It can identify whether the problem is wear time, sensor contact, battery, synchronization, source conflict, or an unstable baseline. It can then offer one or two checks instead of a long troubleshooting list. The user should not have to inspect every setting before learning which condition actually prevented the score.
The app should preserve the gap as a gap. Backfilling it later may be appropriate when a delayed source arrives, but the history should distinguish a late record from a measurement collected at the original time. This protects trend interpretation and makes future corrections reviewable.
The message should also explain whether the next complete period is enough or whether several comparable observations are needed. A readiness score that depends on a baseline cannot become reliable merely because one missing night was restored. The value of a validation result depends on its conditions, and the user's next step should match that limitation.
Withholding a score is therefore an active design choice. It guides the user toward better data without pretending that a number can replace the missing evidence. A missing-input state should be explicit, and a delayed record should remain marked as delayed. This keeps the output honest and the history reviewable.
FAQ
Why would a readiness score be withheld?
The required inputs may be missing, conflicting, or too noisy to support a comparable estimate. The app should show which condition applies and what, if anything, the user can do next.
Is “not enough data” better than a low score?
Yes when the system cannot justify a score. A low score implies that the calculation ran on valid inputs and that the result is interpretable. A withheld score is more honest when that assumption is not met.
Can I make a decision without a readiness score?
Yes. Review the quality of the available record, recent context, symptoms, function, and the decision you planned to make. Treat the missing score as a limitation, not as a hidden recommendation.
*This article is for informational purposes only and is not a substitute for professional medical advice, diagnosis or treatment.*
Sources:
U.S. National Library of Medicine·U.S. Food and Drug Administration·U.S. Food and Drug Administration·EQUATOR Network·PubMed·U.S. National Library of Medicine
Related articles

How to Separate Local Muscle Fatigue From Whole-Body Recovery
Whole-body recovery metrics and local muscle fatigue can point in different directions because they describe different systems. Learn how to keep both layers in the record and choose a training decision that matches the limiting factor.

What a Wearable Can and Cannot Tell You About Delayed Muscle Soreness
Delayed muscle soreness often appears after the workout that caused it, while wearable metrics may change on another schedule. Learn what a device can add, what it cannot measure directly, and how to record the local response.

What Overnight Recovery Data Can Show After Intervals
Overnight recovery data can show how the body responded after interval work, but it cannot grade the workout or predict the next session by itself. Learn how to read overnight timing, heart-rate variability, sleep, and daytime function together.

Why Arm-Dominant Cardio Can Look Easier Than It Feels
Arm-dominant cardio can produce substantial local effort without looking like a conventional lower-body workout on a wearable. Learn how to pair heart rate with perceived exertion, local fatigue, duration, and the movement performed.

How Low Power Mode Can Break Overnight Recovery Data
Low power mode can preserve a sleep interval while reducing the overnight signals a recovery score needs. This guide explains the tradeoff, how to test it safely, and how to label an incomplete night.

Why a Recovery Score Can Go Missing Even When Sleep Is Recorded
A recorded sleep session does not guarantee that a recovery score has every input it needs. This guide explains how overnight signals, baselines, timing, and data quality can separate the two results.

What a Readiness Percentage Cannot Tell You About Injury Risk
Many readiness systems depend on overnight measurements that daytime spot checks cannot replace. Before interpreting the score, confirm that the night was recorded well enough to support it.

Why Cardio and Strength Need Different Readiness Decisions
Readiness scores often summarize cardiovascular, autonomic, sleep, and movement signals, while local muscle soreness can remain outside the calculation. Use both kinds of information when choosing a session.

What a Readiness Score Leaves Out About Muscle Soreness
Readiness scores often summarize cardiovascular, autonomic, sleep, and movement signals, while local muscle soreness can remain outside the calculation. Use both kinds of information when choosing a session.

Why a Readiness Score Can Stay Low After a Rest Day
An intraday readiness score is a moving estimate, not a permanent morning label. Learn which new inputs can change it, when the update is informative, and when it should not alter your plan.